Turn your own photo, an original character or an AI-generated fictional portrait, plus one audio track, into a video of that character speaking or singing. Up to 5 minutes in a single take.
1
Portrait
2
Voice
0/300
Add a portrait and a voice track to continue.
Free preview · limited generations per hour · 720p · audio 4 s – 5 min · Own or consented photos only, no impersonation of real people.
See how it works Powered by OmniHuman 2.0, available via BytePlus · Independent site
Get early access updates
One continuous take
0:00 / 0:00
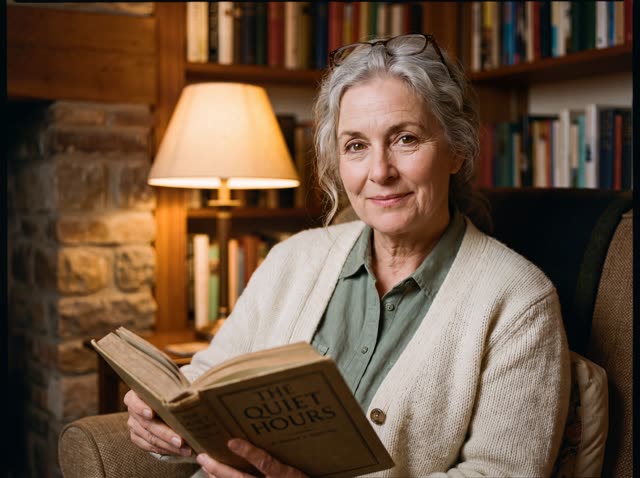
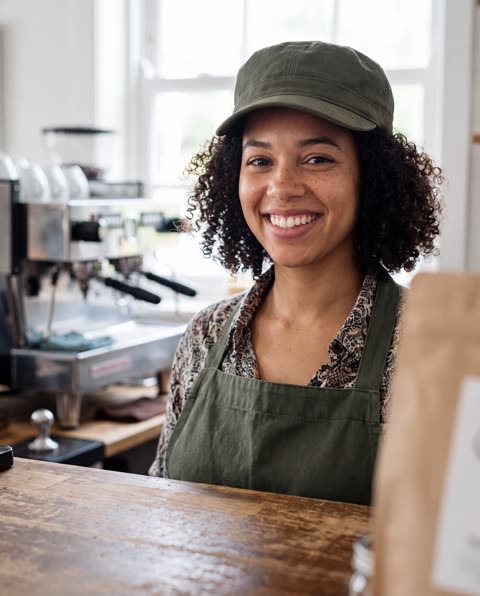
Lip sync
0:00 / 0:00
Song
0:00 / 0:00
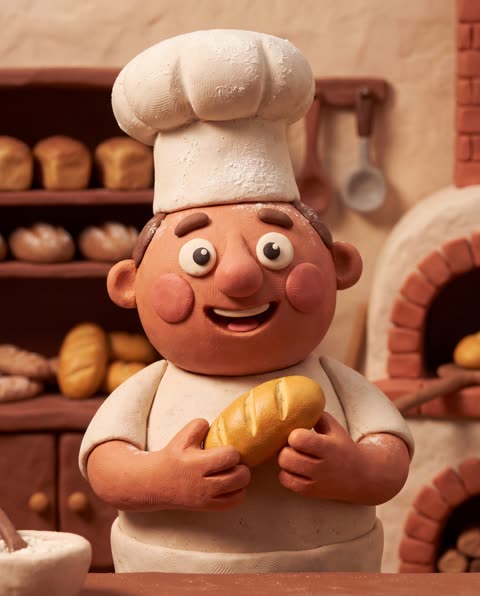
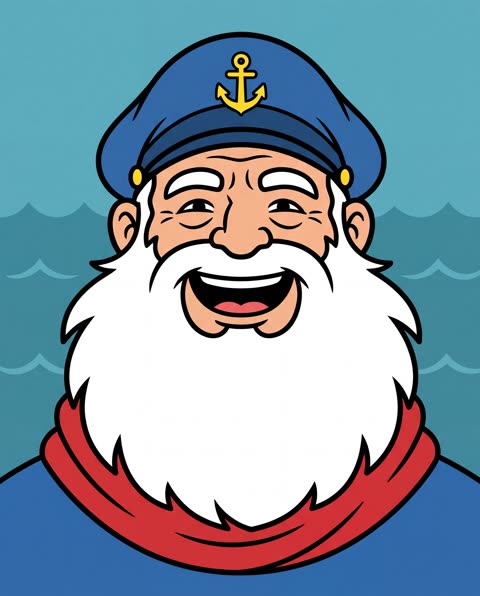
Drawn character
0:00 / 0:00
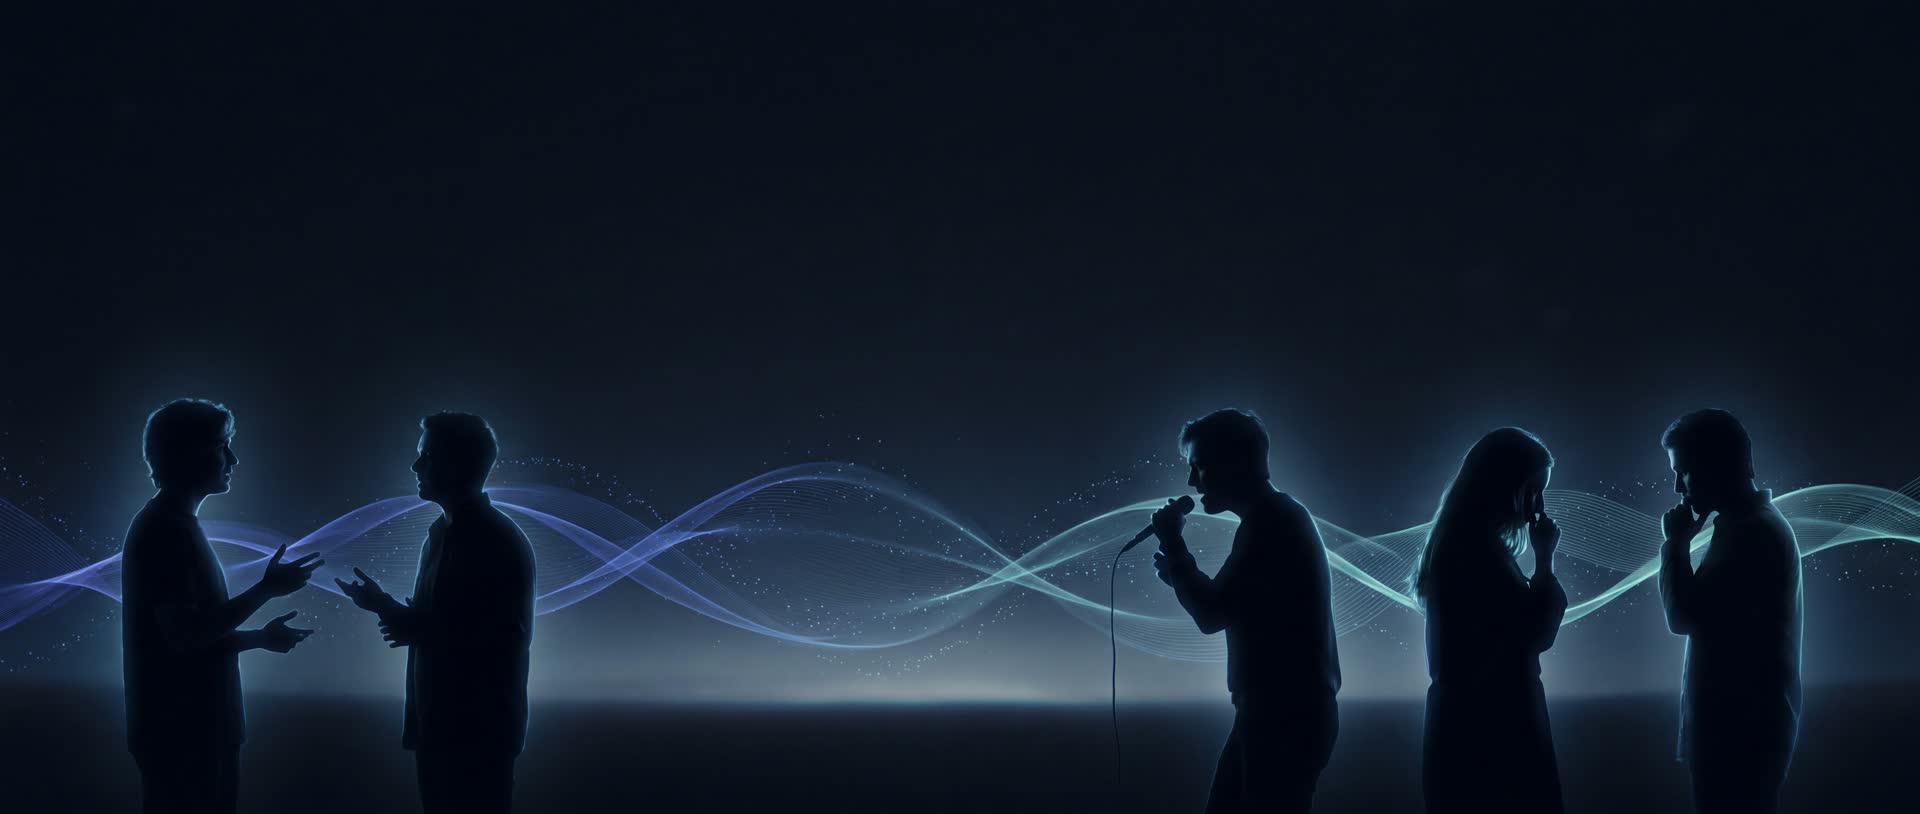
Dialogue
0:00 / 0:00
Single take(was 0:60)
5:00
Photo + audio
1+1
Stitching
0
Speech · song · dialogue
3-in-1
Courses & lessons
Explainers
Music clips
Mascots
Reels & Shorts
Podcasts
Dialogue
Clay characters
Audiobooks
Product demos
Courses & lessons
Explainers
Music clips
Mascots
Reels & Shorts
Podcasts
Dialogue
Clay characters
Audiobooks
Product demos
How it works
Three steps. No timeline.
No rigging, no keyframes, no separate singing mode. Bring your own face or an original character and a sound — the model does the performing.
1
portrait.jpg
Upload your own photo
A selfie, a portrait of someone who has given you consent, an original clay or drawn character, or an AI-generated fictional portrait. A plain background and a single clear face work best.
2
Add one audio track
Speech, a song, or a dialogue — it's all the same input. There's no separate singing mode to switch on.
3
output.mp4
Get the performance
OmniHuman 2.0 renders a video of that character performing the audio — face, head and body — in one continuous take of up to 5 minutes.
TIP — a plain background and a single clear face give the best results. Only use photos you own or have consent for.
Features
It listens to how it's said.
OmniHuman 2.0 hears tone, emotion and words — and turns all three into a believable on-camera performance.
5:00
Previous version0:60 max
OmniHuman 2.05:00 · one take
Up to 5 minutes, one take
The previous version capped out at 60 seconds. Now you get up to 5 minutes rendered continuously — no stitching.
laughwhisperpauseemphasis
Hears tone, not just words
The model listens for emotion and delivery. Laughs, whispers and pauses show up on the face, not just in the soundtrack.
ev
ery
syl
la
ble
Every syllable lands
Mouth shapes follow each syllable — including fast lines and long held notes in songs.
Face
Head
Body
A full performance
It generates face, head and body motion together, so the result reads as a performance rather than a pasted-on mouth.
Stitched clips — visible cuts
One take — continuous
No jumps, no seams
Because nothing is stitched together, there are no sudden shifts in the face, the lighting or the background mid-video.
photo
clay
drawn
Your own or fictional
Works with your own selfies and consented portraits, AI-generated fictional people, clay figures, drawn characters and brand mascots. Never real or famous people without their consent.
SpeechSongDialogue
Same input. No singing mode.
Speech, song or dialogue
One model handles narration, singing and conversation. Just bring the audio — the model figures out the rest.
↓ cost
vs. previous version · per BytePlus
Cheaper to run
According to BytePlus, OmniHuman 2.0 is cheaper to run than the previous version — which means more minutes for your budget.
Spec sheet
The model, at a glance.
Everything OmniHuman 2.0 needs, and everything it gives back.
Modes
Speech · Song · Dialogue — one input, no separate singing mode
Length
Up to 5 minutes in one continuous take (previous version: 60 seconds)
Input
1 photo — your own or consented portrait, original clay/drawn character, or an AI-generated fictional person
Audio types
Narration, singing (fast lyrics, held notes), conversation
Output
Face, head and body performance video · no stitching
Model
OmniHuman 2.0 by ByteDance, available via BytePlus
Before / after
Not just lip sync. A performance.
Typical lip-sync tools animate a mouth. OmniHuman 2.0 animates a person.
Plain lip sync
Before
Mouth only
What moves
Mouth region only
Reacts to emotion & tone
No
Laughs, whispers & pauses on the face
No
Fast lines & held notes
Often drifts
Singing
Separate tool or mode
Clip length
Short clips, stitched
Face / lighting / background consistency
Can jump between segments
Drawn, clay & mascot characters
Limited
OmniHuman 2.0
After
Face · head · body
What moves
Face, head and body
Reacts to emotion & tone
Yes
Laughs, whispers & pauses on the face
Yes
Fast lines & held notes
Follows every syllable
Singing
Same input — no singing mode
Clip length
Up to 5 min in one take
Face / lighting / background consistency
Continuous, no stitching
Drawn, clay & mascot characters
Yes
Use cases
Made for anything with a voice.
From five-minute stories to fifteen-second shorts. Portraits by Nano Banana 2.1, voices by ElevenLabs, video by OmniHuman 2.
Made with OmniHuman 2.0 · Education
Courses & lessons
Turn a script and an instructor photo into long-form lessons — up to 5 minutes per take. This sample is a calm, outdoor gardening lesson.
Hover or scroll to preview · generated with OmniHuman 2
Pricing
Simple plans. Cancel anytime.
Two simple monthly plans, shown in full before you pay. Checkout is handled securely by Creem.io.
Starter
$9.99/month
Billed monthly
35 credits per month
= 35 seconds of video every month.
1 credit = 1 second of video
4 s minimum, 120 s maximum per video
Failed generations are refunded
Credits don't roll over
Cancel anytime
Pro
Popular
$29.99/month
Billed monthly
120 credits per month
= 120 seconds of video (2 min) every month.
1 credit = 1 second of video
4 s minimum, 120 s maximum per video
Failed generations are refunded
Credits don't roll over
Cancel anytime
Prices in USD. Taxes calculated at checkout by Creem.io. Credits renew monthly and do not roll over.
Responsible use: all plans are for your own or explicitly consented photos and for original or fictional characters. Impersonating real people or celebrities, deepfakes and voice cloning are prohibited and prompts naming real people are blocked. See the Acceptable Use Policy.
FAQ
Questions, answered.
Can't find what you need? Everything about inputs, length and availability is here.
01What is OmniHuman 2.0?
OmniHuman 2.0 is ByteDance's audio-driven human video model, released via BytePlus on October 15, 2026. You give it one photo you own (or have consent to use) and one audio track, and it generates a video of that character performing the audio.
02What do I need to make a video?
Just two things: a single photo and a single audio track. The photo must be your own, of someone who gave you explicit consent, or of an original or AI-generated fictional character. The audio can be speech, a song or a dialogue. You confirm this with a required consent checkbox before every upload.
03Is there a separate mode for singing?
No. Singing uses exactly the same input as speech — upload the song and the model handles it, including fast lyrics and long held notes.
04How long can a video be?
The OmniHuman 2.0 model supports up to 5 minutes in one continuous take (the previous version was capped at 60 seconds), and the video isn't stitched from shorter pieces, so the face, lighting and background stay consistent. On OmniHuman2.net each video is 4 to 120 seconds long.
05Is this just lip sync?
No. Plain lip sync only moves the mouth. OmniHuman 2.0 generates the face, head and body performance, and it reacts to tone and emotion — so laughs, whispers and pauses show on the face.
06Can I use a cartoon, clay figure or mascot?
Yes. Besides your own selfies and consented portraits, it works with original clay and drawn characters, mascots and AI-generated fictional portraits.
07How do I get the best results?
Use a photo with a plain background and a single, clearly visible face. Clean audio without heavy background noise also helps.
08Can I use a photo or voice of a celebrity or another real person?
No. You may only use your own photo and voice, or those of a person who has given you clear, explicit consent. Impersonating celebrities, public figures or other real people, deepfakes, face swaps and voice cloning are prohibited, prompts that name or imitate real people are blocked, and text-to-voice only offers stock synthetic voices. See our Acceptable Use Policy.
09Do I need an account?
Yes. Create a free account, then pick a plan. Starter is $9.99/month and includes 35 credits (35 seconds of video per month). Pro is $29.99/month and includes 120 credits (2 minutes of video per month). Both are billed monthly and you can cancel anytime from your dashboard.
10How do credits work?
1 credit = 1 second of generated video, rounded up to the next full second, with a 4-second minimum and a 120-second maximum per video. Credits are reserved when a video starts and refunded automatically if it fails. Credits renew with each monthly payment and unused credits do not roll over. A generated voice from text costs 1 credit per 100 characters.
11Is this site affiliated with ByteDance?
No. OmniHuman2.net is an independent product built on third-party AI models. It is not affiliated with, endorsed by, or sponsored by ByteDance, BytePlus, fal.ai or ElevenLabs. All trademarks belong to their respective owners. NSFW, explicit, illegal content, deepfakes and impersonation of real people are prohibited — see our Acceptable Use Policy.
One photo · one track · up to 5:00
Give your audio a face.
One photo, one track, up to five minutes of continuous performance.

 Mouth only